Category: Other

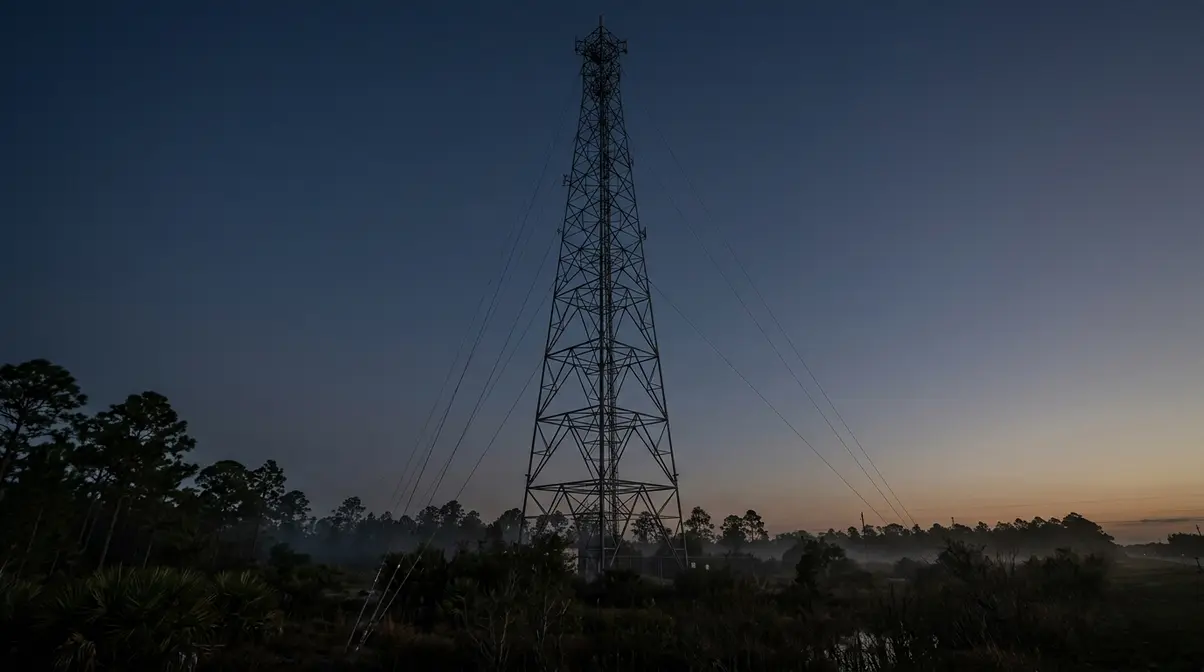
  • Pilot killed in Florida helicopter collision with radio tower

    Pilot killed in Florida helicopter collision with radio tower

    A fatal aviation incident occurred in Florida involving a helicopter engaged in mosquito control operations. The aircraft collided with a radio tower, resulting in the death of the pilot. According to reports, the radio tower involved in the collision was unlit at the time of the accident.

    Source: Data Center Dynamics
    Original article: https://www.datacenterdynamics.com/en/news/mosquito-control-helicopter-crashes-into-radio-tower-in-florida-killling-pilot/

  • A dataset of formalised theorem statements from the Annals of Mathematics

    A dataset of formalised theorem statements from the Annals of Mathematics

    arXiv:2610.18301v1 Announce Type: new Abstract: Recent progress in autoformalisation of mathematics using AI has been impressive. Measuring this progress requires datasets of formal statements that are both hard and trustworthy. We present AnnalsChallenge: 50 formalised theorem statements written by hand in Lean 4 using Mathlib. Each is the main result of a paper published in the Annals of Mathematics since 2020. Every formalisation was manually reviewed and then audited by AI. We release them without formalised proofs.

    Fallback brief based on the available RSS feed; no unsupported details have been added.

    Source: arXiv
    Original article: https://arxiv.org/abs/2610.18301

  • Neuro-Symbolic Graph Transformers for Hierarchical Intention Recognition from Multimodal Human Activity Sequences

    Neuro-Symbolic Graph Transformers for Hierarchical Intention Recognition from Multimodal Human Activity Sequences

    arXiv:2610.18176v1 Announce Type: new Abstract: Proactive human-robot collaboration requires autonomous systems to infer not only immediate actions but also the underlying hierarchical intentions governing human behavior. Current deep learning approaches predominantly focus on flat action classification, failing to capture the structural dependencies connecting kinematic motion to high-level goals. A Neuro-Symbolic Graph Transformer (NSGT) is proposed within this multimodal framework, a Human Reasoning Graph (HR-G) is integrated into the self-attention mechanism via learnable topological biases. Furthermore, the architecture is augmented with a differentiable First-Order Logic (FOL) loss, acting as a structural regularizer by which ontological consistency is enforced across four levels: atomic actions, composite activities, Low-Level Intentions, and High-Level Intentions. Evaluation is performed on the synthesized NTU-Hierarchy dataset, a four-level ontological extension of NTU RGB+D 120, wherein existing sequences were mapped into 119,383 complex hierarchical episodes (85 actions, 16 activities, 8 LLIs, 4 HLIs). To prevent circular supervision, strict isolation between label generation and FOL constraints was maintained. In the base configuration, 91.65% top-1 action accuracy is achieved by the NSGT. When the FOL loss is incorporated into the baseline, logic consistency is improved by 3.26 percentage points to 96.67%. Through the HR-G biases, a tunable trade-off between accuracy and structural coherence is established. In the primary consistency-maximizing configuration ($\lambda$ = 0.5), a logic consistency of 94.59% is reached and ontological contradictions are reduced by 33%, while a robust 89.90% top-1 action accuracy is retained. Finally, interpretable reasoning evidence is provided by the learned HR-G weights, wherein transition edges are strongly exploited ($\beta$ trans $\approx$ +2.6) without explicit supervision.

    Fallback brief based on the available RSS feed; no unsupported details have been added.

    Source: arXiv
    Original article: https://arxiv.org/abs/2610.18176

  • QORH: Learning Query-Specific Ordered Rule Hypergraphs for Inductive Knowledge Graph Link Prediction

    QORH: Learning Query-Specific Ordered Rule Hypergraphs for Inductive Knowledge Graph Link Prediction

    arXiv:2610.18198v1 Announce Type: new Abstract: Knowledge graph link prediction involving unseen entities and relations requires learning transferable reasoning patterns from observed graph structure. Existing methods based on relation graphs primarily capture pairwise dependencies, limiting their ability to preserve the compositional semantics, relation ordering, and role information of complete path rules. To address this limitation, we propose QORH (Query-specific Ordered Rule Hypergraph), which jointly encodes rule heads and ordered rule bodies as hyperedges conditioned on the query relation, explicitly modeling joint dependencies among multiple relations. QORH performs learnable rule selection using statistical evidence, such as rule confidence and coverage, and enhances relation representations through role-aware hypergraph message passing to guide entity-level reasoning. The model's shared parameters are independent of specific entity or relation identifiers, enabling inductive prediction for unseen entities and relations. Extensive experiments on entity-inductive and fully inductive benchmarks demonstrate that QORH significantly outperforms the state-of-the-art baselines included in our evaluation, validating the effectiveness of rule hypergraph modeling for inductive link prediction.

    Fallback brief based on the available RSS feed; no unsupported details have been added.

    Source: arXiv
    Original article: https://arxiv.org/abs/2610.18198

  • Consider, Then Choose: Order-Invariant Decisions in System One Models

    Consider, Then Choose: Order-Invariant Decisions in System One Models

    arXiv:2610.18233v1 Announce Type: new Abstract: System One models answer typed questions in a single forward pass and promise the same answer for the same input. For choice questions, this promise fails: the answer depends on the order of the options, increasingly so as they grow in number, and averaging over their cyclic shifts reduces this dependence without removing it. Scoring each option alone, which the order cannot affect, shows that the order changes the answer mostly when the model is unsure among its top few options, even though the listwise answer looks confident. We therefore propose $\textbf{Runoff}$, which considers, then chooses: it scores each option alone to keep a few candidates, then compares them in listings where each candidate takes every position. It needs no training and can run in two forward passes, and its answer does not depend on the option order by construction. On two open models and five datasets, it changes no answer under shuffling, against 9.3% for cyclic averaging, and with 20 options it is about as accurate and three to four times faster. Wrapped around eight System One models, it removes the order dependence of the five benchmarks, while cyclic averaging changes up to 15.4%.

    Fallback brief based on the available RSS feed; no unsupported details have been added.

    Source: arXiv
    Original article: https://arxiv.org/abs/2610.18233

  • RadixFlow: Filling Execution Bubbles in Prefix-Cached Hybrid LLM Serving

    RadixFlow: Filling Execution Bubbles in Prefix-Cached Hybrid LLM Serving

    arXiv:2610.18143v1 Announce Type: new Abstract: Prefix reuse improves LLM inference by sharing the KV cache of common prompt prefixes. This helps only if the scheduler can execute a matched branch in the current worker round. Schedulers assume that a matched prefix is ready, which holds for full attention but fails for hybrid LLMs. There, a branch (the consumer) may need recurrent state that another branch (the producer) is still computing in the same round. The native scheduler stops its waiting-queue scan at this blocked consumer, and the resulting head-of-line blocking creates \emph{execution bubbles}: idle batch slots that independent work could fill. We introduce RadixFlow, which decouples prefix matching from state readiness. Its state-ready traversal turns a global scan barrier into a local wait: only the consumer is blocked until the next round, while feasible independent branches keep filling the batch under the native state check. On five hybrid models, RadixFlow lowers mean latency by 3\% to 24\% and worker rounds by 11\% to 44\% at almost unchanged reuse. On the larger Qwen3.5 models, ablations show that most of the gain comes from traversal, which adds little on a full-attention control. Heavier rounds limit how much of this saving reaches latency.

    Fallback brief based on the available RSS feed; no unsupported details have been added.

    Source: arXiv
    Original article: https://arxiv.org/abs/2610.18143

  • When and How Order-Flow Interventions Work After Dealers Adapt

    When and How Order-Flow Interventions Work After Dealers Adapt

    arXiv:2610.18158v1 Announce Type: new Abstract: Learning dealer agents can settle on persistently wide quotes, raising what customers pay to trade. A venue can route more orders to tighter quotes, but a wide quote may reflect real risk, and once dealers adapt, an end-to-end comparison cannot show why a rule works: because it intervenes more, picks better moments, is announced in advance, or rewards the right quote. We propose SOFA (State-aligned Order-Flow Allocation), a public order-flow contract with three parts: a State Scorer ranks market states from lagged public data, a Commitment Scheduler announces a budgeted intervention strength before dealers quote, and a Quote-to-Flow Allocator shifts a bounded share of fixed customer demand toward tighter quotes. Our paired re-adaptation protocol gives competing rules the same intervention strengths, only re-timed, lets dealers re-adapt to each rule from a shared checkpoint, and breaks one link at a time. Across 20 independently trained dealer populations in an ABIDES market, concentrating the intervention in states that the score ranks as low-risk lowers low-risk execution cost relative to random timing in every population, by 0.040 tick on average, while a stale announcement or a broken quote-to-flow link raises this cost. In the primary setting the gain comes at the expense of high-risk trades, whose costs rise, so state alignment pays off only for a venue that weighs low-risk costs more than 1.38 times as heavily as high-risk costs. Our code is available at https://github.com/moderncavemann/state-aligned-order-flow-contracts.

    Fallback brief based on the available RSS feed; no unsupported details have been added.

    Source: arXiv
    Original article: https://arxiv.org/abs/2610.18158

  • Back to the Future: Reverse-Consequence Modeling for Long-Horizon Particle Dynamics

    Back to the Future: Reverse-Consequence Modeling for Long-Horizon Particle Dynamics

    arXiv:2610.18168v1 Announce Type: new Abstract: Accurate prediction of object trajectories is fundamental to mechanical understanding and robotic control. However, autoregressive models inherently suffer from cumulative errors, leading to severe drift in long-horizon rollouts. Observing that in many physical systems with dissipative or convergence-to-rest behavior, the final states are often more predictable than transient dynamics (e.g., a sliding object resting under friction or a pendulum stabilizing at equilibrium), we propose ReStep, a cascaded approach that reverses the conventional forward-prediction paradigm. ReStep first employs a stochastic model to directly predict the final state, then leverages Anchored Diffusion to generate goal-conditioned intermediate trajectories. By conditioning on both ''boundary states'', it effectively constrains dynamics and reduces uncertainty, producing physically plausible and temporally coherent transitions. We further integrate ReStep dynamics as the physical engine within a 3D Gaussian Splatting pipeline, enabling a unified physical-visual framework for intuitive inference from images. Extensive experiments on diverse rigid and non-rigid collision datasets show that ReStep achieves superior long-term accuracy, substantially mitigating error accumulation via reverse-consequence modeling.

    Fallback brief based on the available RSS feed; no unsupported details have been added.

    Source: arXiv
    Original article: https://arxiv.org/abs/2610.18168

  • Chain of Thought Monitoring Can Fail Even When CoT Is Necessary

    Chain of Thought Monitoring Can Fail Even When CoT Is Necessary

    arXiv:2610.18105v1 Announce Type: new Abstract: Chain of Thought (CoT) monitoring is used by frontier labs to detect misbehaviour of AI systems. Yet, its reliability remains poorly understood. We attribute this to the lack of a successful organizing principle that leads to generalizable conclusions about monitoring reliability in different regimes. Recent work attributes monitoring failures to the CoT not being necessary for the answer, and argues that CoT becomes monitorable when it is necessary. We show that this binary necessary/not-necessary organizing principle is too coarse by demonstrating that monitoring failures persist even if the CoT is necessary for the answer. In response, we introduce a more fine-grained organizing principle based on a hierarchy of four CoT necessity levels. Building on this hierarchy, we develop a framework for measuring CoT monitorability at the three lowest levels via intervention experiments. We demonstrate monitoring failures at all three of these levels on realistic, hard prediction tasks. On a difficult medical-diagnosis task, patient sex and a clinical attribute influence the answer in at least 19% and 24% of correct responses with a necessary CoT, respectively, yet their influence is almost never articulated. These results show that even when CoT is necessary, it is not guaranteed to be monitorable.

    Fallback brief based on the available RSS feed; no unsupported details have been added.

    Source: arXiv
    Original article: https://arxiv.org/abs/2610.18105

  • Fresh at Decision, Stale at Action: Routing New Information to LLM Decisions Already Made

    Fresh at Decision, Stale at Action: Routing New Information to LLM Decisions Already Made

    arXiv:2610.18126v1 Announce Type: new Abstract: Freshness shapes an LLM decision at the moment it is made; the action it commits to is latent, carried out later, in a changing world. We therefore introduce a timestamp theory of decision validity and a decision ledger that realises it. Six timestamps define a decision; a freshness ceiling bounds what up-to-date evidence guarantees at action time, placing the remaining risk in information published afterwards. Accuracy then factorises into two capabilities: routing, which delivers that information to affected decisions before their revision deadlines, and temporal judgment, which reads it for the time of action. The ledger is persistent state holding each decision's times, evidence and background knowledge, indexed by watch conditions written at decision time. Controlled decision streams with exact labels confirm four predictions across five LLMs, from 8B to frontier scale: freshness alone yields exactly the accuracy the ceiling predicts; models act on decisive news once it arrives, so accuracy follows routing; the ledger's index sets what routing reaches, and watch conditions reach indirect dependencies at low exposure; and the remaining errors concern when a change takes effect. Freshness makes a decision right when it is made; routing and temporal judgment keep it right when it is carried out.

    Fallback brief based on the available RSS feed; no unsupported details have been added.

    Source: arXiv
    Original article: https://arxiv.org/abs/2610.18126